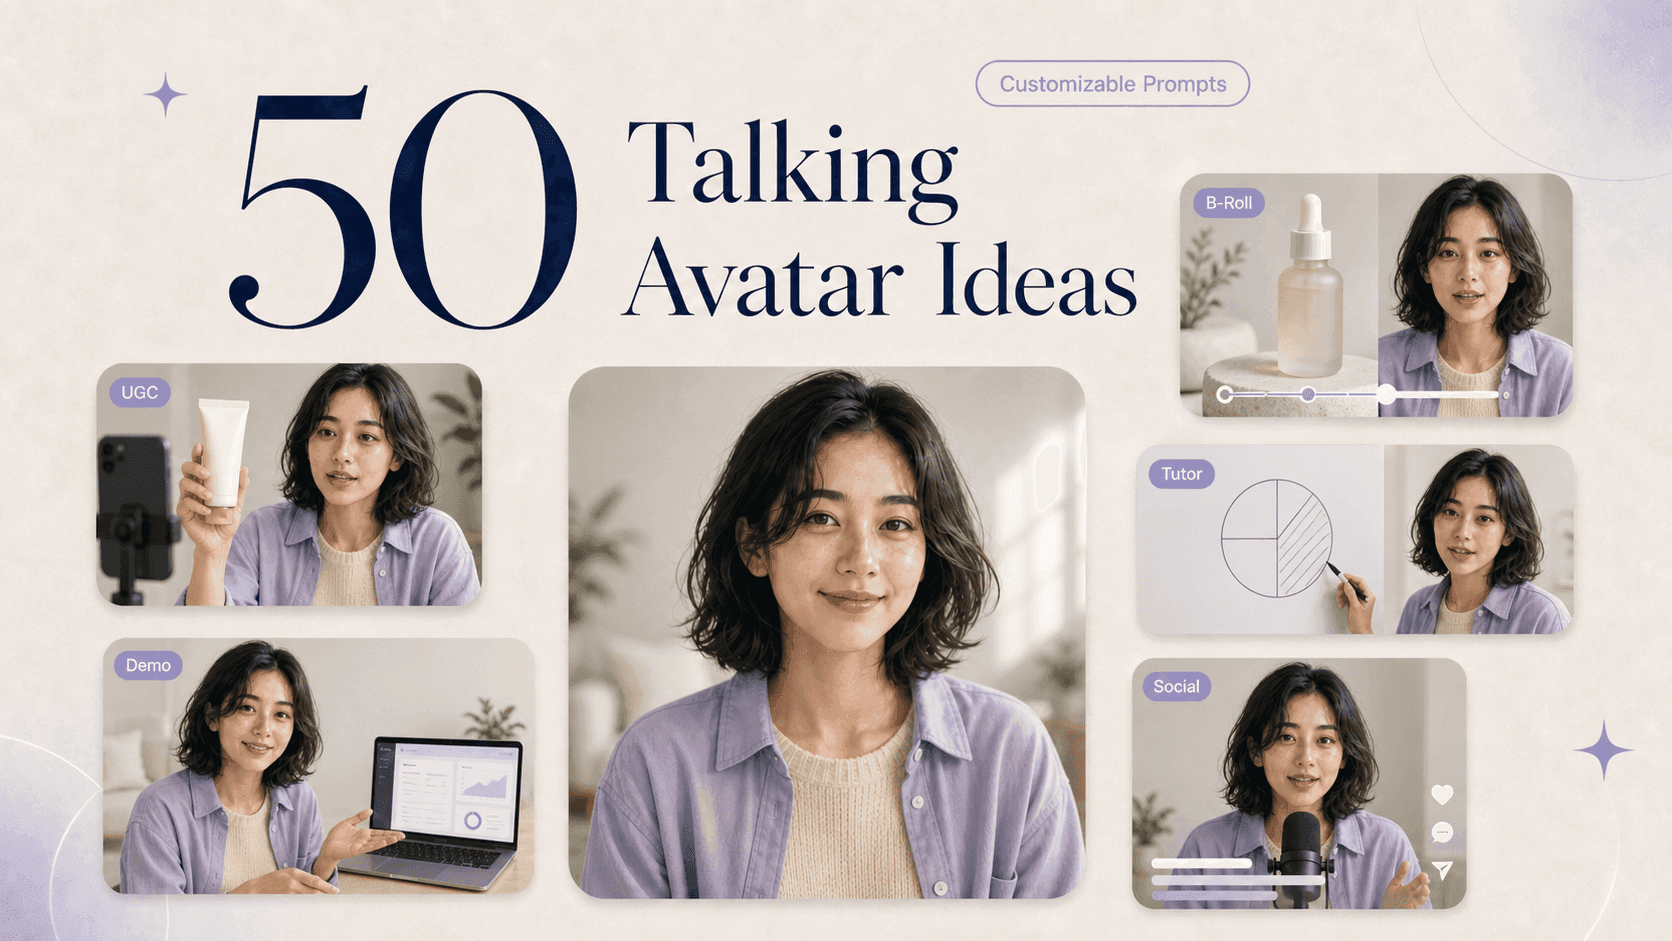
The best talking avatar video ideas give the speaker a clear job. This guide groups 50 ideas by persuasion angle, visual layout, teaching method, product task, and publishing format. Each one includes a customizable input pack, production notes, replaceable variables, and objective checks.
Making a face speak is only the starting point. You still need the right message, supporting footage, performance direction, and next action. Pick one idea below, replace its variables, and build a short pilot before expanding it into a full video.
Testing note: We tested a small selection of these prompts in DomoAI. Use the full collection as inspiration and a starting point for your own videos, rather than expecting identical results. Adapt each prompt to your source image, audio, and use case, then test a short pilot before scaling the format.
How to Choose and Use These Talking Avatar Prompts
Start with the decision you need to make. Do not choose a format only because its sample product resembles yours.
| If you need to decide… | Start with… | What changes between ideas |
|---|---|---|
| How the message persuades | UGC Ad Concepts | Objection, evidence, framing, and CTA |
| How the presenter and supporting footage share the screen | Product B-Roll Layouts | Timing, screen space, and cut order |
| How the lesson teaches | AI Tutor Ideas | Learning objective, learner action, and knowledge check |
| How to explain a product task | Product Demo and Explainer Ideas | Feature, workflow, evidence, and user question |
| What you can publish repeatedly | Social and Creator Formats | Episode structure, cadence, and source process |
If you need character-led concepts instead, explore these anime, pet, VTuber, and mascot avatar ideas. This page stays focused on ads, layouts, lessons, product explanations, and recurring creator formats.
What Goes Into the Script, Action Prompt, and Edit Timeline
“Prompt” in this guide means a small production input pack. It is not one paragraph pasted into one field.
| Input-pack part | Where it belongs |
|---|---|
| Host image or video | Talking Avatar visual input |
| Spoken wording | Uploaded permitted audio or DomoAI Text to Speech |
| Smile, gaze, nod, head turn, or restrained gesture | Separate action/expression prompt |
| Target aspect ratio | Delivery and editing plan |
| B-roll, screen capture, captions, music, proof, and end card | Supporting generation or external edit |
| Custom-background composite | Screen Keying and an editor when needed |
The action prompt should describe visible speaking behavior. It should not repeat the full script or ask the avatar to assemble an entire ad. Use DomoAI Talking Avatar for the presenter clip, then add the supporting material in your editing timeline.
A useful action arc is simple:
Initial pose → one small opening movement → two or three visible speaking cues → a clean closing hold
Only request movements the source frame can show. If the image ends at the shoulders, do not add hand gestures. Keep the background stable and avoid competing camera directions.
Replace Only the Variables the Idea Uses
You will see variables such as:
[avatar role] [target audience] [product or topic] [problem or question]
[verified benefit or learning outcome] [tone] [video length]
[target aspect ratio] [supporting asset] [proof] [CTA or ending]
Replace every listed variable before generating. Remove any field you cannot support with accurate material. A verified product clip is stronger than a detailed instruction asking an avatar to pretend it used the product.
Change One Variable at a Time
Keep your first test small. Generate one presenter segment, review it, then change one variable. You might revise the script length, eye line, gesture, source image, or B-roll timing.
If you change everything together, you cannot tell what fixed the problem. The broader DomoAI workflow guide can help when an idea needs Image to Video, Frames to Video, or another tool beyond Talking Avatar.
15 UGC Ad Ideas With an AI Avatar Spokesperson
These UGC-style concepts use a disclosed brand presenter or fictional host, not someone claiming real customer experience. Build each Talking Avatar clip from an owned image or video and TTS or permitted audio. Add proof footage, captions, comparison cards, and end screens during editing. Replace every bracketed claim with approved, current information before production.
1. Problem–Solution Ad
Best for: Products addressing one clear, documented customer problem.
Concept: Use a disclosed brand presenter to name one familiar problem and connect it to one documented product capability. The avatar frames the claim; owned footage or a sourced product screen supplies proof. Keep one problem-benefit pair so viewers can judge fit without a fictional customer story, personal experience, or promised outcome.
Video structure: Problem → verified response → proof → CTA.
Prompt — copy-ready input pack:
- Setup: Create a 20-second disclosed brand-guide clip for [audience], planned for 9:16 [platform], in a front-facing medium shot.
- Spoken script/audio brief: Name [problem], explain that [verified capability] may help with [task], then invite viewers to [CTA].
- Action/expression prompt: Lift the brows on [problem], nod after [verified capability], then end neutral. Keep framing, background, and lighting stable.
- Edit/CTA cue: Add [proof] beneath the capability line, concise captions, and the [CTA] end card.
Replaceable variables: [audience], [platform], [problem], [verified capability], [task], [proof], [CTA].
Production note: Verify the capability against current product documentation.
Success check:
- Is the problem stated before the product?
- Does the proof support the stated benefit?
2. Discovery-Style Product Introduction
Best for: Introducing an unfamiliar product without invented personal experience.
Concept: Use a fictional shelf guide to explain what an unfamiliar product is and when it may fit. Curiosity comes from a useful category clue, not a claim that the speaker found, bought, or tested it. Name the product once, show an owned product view, and send interested viewers to a factual overview.
Video structure: Category clue → product type → use case → overview.
Prompt — copy-ready input pack:
- Setup: Make a 10-second fictional guide for [new audience], planned for 9:16 [platform], in a medium shot.
- Spoken script/audio brief: Open with [category clue]. Introduce [product] as a [verified type] designed for [use case]. Point viewers to [CTA].
- Action/expression prompt: Lift the brows on [category clue], nod after [verified type], then settle calmly. Preserve the crop, backdrop, and light level.
- Edit/CTA cue: Cut to [owned product view], add a factual label, and close on [CTA].
Replaceable variables: [new audience], [platform], [category clue], [product], [verified type], [use case], [owned product view], [CTA].
Production note: Keep the product name to one spoken mention.
Success check:
- Is the fictional guide role clear?
- Does the introduction avoid lived-experience claims?
3. Three Reasons to Try It
Best for: Decision-stage buyers needing a quick product summary.
Concept: Give a disclosed brand presenter three distinct, verified reasons to consider the product. Each reason should answer a different buyer question, such as fit, workflow, or support. Keep the order meaningful rather than listing three versions of the same claim. Add one approved proof visual for each reason during editing.
Video structure: Audience fit → three ranked reasons → next step.
Prompt — copy-ready input pack:
- Setup: Generate a 20-second brand-presenter clip for [buyer], planned for 9:16 [platform], with a stable medium close-up and visible mouth.
- Spoken script/audio brief: Introduce [product], then state [reason one], [reason two], and [reason three] in short lines. Close with [CTA].
- Action/expression prompt: Pause between reasons, nod after [reason three], then hold the closing gaze. Keep the camera, backdrop, and exposure steady.
- Edit/CTA cue: Add numbered captions, [proof set], and a final [CTA] card.
Replaceable variables: [buyer], [platform], [product], [reason one], [reason two], [reason three], [proof set], [CTA].
Production note: Read the script aloud and move excess detail into captions.
Success check:
- Do the reasons answer different buyer questions?
- Can each reason be verified?
4. Evidence-Based Before-and-After Explanation
Best for: Documented changes with approved baseline and outcome evidence.
Concept: Use the avatar to explain a verified comparison between a recorded baseline and a later measured state. Focus on the documented process change, not a dramatic transformation. The presenter supplies context, while dated and equally framed evidence carries the comparison. Use this format only when the owner approves the method, labels, and result language.
Video structure: Baseline → process change → measured state → source.
Prompt — copy-ready input pack:
- Setup: Create a 20-second neutral explainer for [audience], planned for 9:16 [platform], using [avatar] in a locked medium shot.
- Spoken script/audio brief: State [baseline], explain [process change], then report [measured state] with [qualifier]. Send viewers to [source].
- Action/expression prompt: Glance toward the comparison area, nod after [measured state], then face camera. Maintain the crop, light direction, and background.
- Edit/CTA cue: Add dated [before evidence] and [after evidence] with equal framing, source labels, and [CTA].
Replaceable variables: [audience], [platform], [avatar], [baseline], [process change], [measured state], [qualifier], [source], [before evidence], [after evidence], [CTA].
Production note: Preserve dates, methods, measurement conditions, and qualifiers.
Success check:
- Are both states sourced and labeled?
- Does the wording stay within the evidence?
5. Myth vs Fact Ad
Best for: Correcting one sourced misconception before a purchase decision.
Concept: Let a calm fact-check host state one misconception briefly, then replace it with a current, sourced fact. Spend more time on the correction than the myth. Add the source title and date during editing so viewers can check the statement. Avoid repeating harmful or misleading wording beyond what is needed to identify it.
Video structure: Myth label → sourced fact → implication → source.
Prompt — copy-ready input pack:
- Setup: Produce a 10-second fact-check clip for [audience], planned for 9:16 [platform], with a clean background and front-facing close-up.
- Spoken script/audio brief: Say, “Myth: [misconception]. Fact: [documented correction].” Explain [practical implication], then direct viewers to [source].
- Action/expression prompt: Tilt slightly on [misconception], pause, nod on [documented correction], then end neutral. Keep the camera fixed; preserve background and lighting.
- Edit/CTA cue: Show Myth and Fact labels, then add [source title], [source date], and [CTA].
Replaceable variables: [audience], [platform], [misconception], [documented correction], [practical implication], [source], [source title], [source date], [CTA].
Production note: Verify the correction and source on publication day.
Success check:
- Does the correction outweigh the myth?
- Does the source support the exact wording?
6. Objection-Handling Ad
Best for: One concrete concern about setup, fit, or effort.
Concept: Start with the buyer’s objection in plain language and answer it in the first spoken line. Follow with one approved fact and a decision cue. A narrow objection makes the answer easier to verify and keeps the presenter from sounding defensive. Use separate clips for unrelated concerns instead of compressing several answers into one ad.
Video structure: Objection → direct answer → proof → next step.
Prompt — copy-ready input pack:
- Setup: Create a 10-second brand-guide clip for [hesitant audience], planned for 9:16 [platform], in a steady front-facing medium shot.
- Spoken script/audio brief: Answer [objection] immediately with [verified answer]. Add [supporting fact], then invite viewers to [CTA].
- Action/expression prompt: Begin attentive, nod after [verified answer], then close calmly. Avoid camera drift, background changes, and light shifts.
- Edit/CTA cue: Place [proof] beside the supporting fact, add its source, and finish with [CTA].
Replaceable variables: [hesitant audience], [platform], [objection], [verified answer], [supporting fact], [proof], [CTA].
Production note: Keep caveats that affect eligibility, setup, or effort.
Success check:
- Does the first line answer the objection?
- Is the proof specific to that answer?
7. Product Comparison Ad
Best for: Choosing between two solution types using shared criteria.
Concept: Compare two generic solution types rather than attacking a named rival. Apply the same approved criteria to both, state a real tradeoff, and explain who each option may suit. The avatar acts as a neutral guide while an edited table shows the evidence. This helps viewers decide without claiming that one choice always wins.
Video structure: Decision → shared criteria → tradeoffs → fit → comparison.
Prompt — copy-ready input pack:
- Setup: Generate a 20-second neutral guide for [audience], for 16:9 [platform], with [avatar] below two columns.
- Spoken script/audio brief: Compare [option A] and [option B] on [criterion one] and [criterion two]. State each fit and tradeoff. Point to [CTA].
- Action/expression prompt: Glance once toward each column, nod, then face center. Lock the crop; keep the background and lighting unchanged.
- Edit/CTA cue: Build an equal two-column table from [verified source] and end with [CTA].
Replaceable variables: [audience], [platform], [avatar], [option A], [option B], [criterion one], [criterion two], [verified source], [CTA].
Production note: Use matching definitions and review dates for both options.
Success check:
- Are the criteria identical for both options?
- Is every comparison point sourced?
8. Skeptic’s Checklist Ad
Best for: Buyers who want to evaluate a product claim themselves.
Concept: Replace a staged skepticism story with a disclosed host and a three-question buyer checklist. Each question should point to evidence the viewer can inspect, such as scope, product fit, or terms. The avatar guides the sequence without claiming a personal change of mind. End by linking to the relevant proof or policy page.
Video structure: Claim → three checks → fit condition → evidence.
Prompt — copy-ready input pack:
- Setup: Make a 20-second checklist host clip for [careful buyer], planned for 9:16 [platform], with a stable medium close-up.
- Spoken script/audio brief: Introduce [claim]. Ask [check one], [check two], and [check three]. Summarize [fit condition], then point to [CTA].
- Action/expression prompt: Pause after each check, lift the brows on [check three], then hold eye contact. Keep camera position, backdrop, and exposure unchanged.
- Edit/CTA cue: Add three numbered cards with [supporting references], then close on [CTA].
Replaceable variables: [careful buyer], [platform], [claim], [check one], [check two], [check three], [fit condition], [supporting references], [CTA].
Production note: Make every check answerable from current evidence.
Success check:
- Can viewers repeat all three checks?
- Does each check point to evidence?
9. Daily Routine Integration
Best for: Showing one realistic product use inside a workflow.
Concept: Place the product at one specific point in a plausible routine, such as a morning admin block. The avatar introduces the task and handoff, while owned B-roll shows the actual product use. Describe the workflow change without promising saved time or better results unless approved evidence supports those claims. Keep the routine narrow and repeatable.
Video structure: Task before use → product handoff → next workflow step.
Prompt — copy-ready input pack:
- Setup: Create a 20-second routine guide for [audience], targeting 9:16 [platform], with [avatar] in a medium shot.
- Spoken script/audio brief: Frame [routine task], explain when [product] enters the workflow, describe [verified handoff], then point to [CTA].
- Action/expression prompt: Glance toward B-roll, nod at [verified handoff], then settle. Hold the frame, seated pose, and background steady.
- Edit/CTA cue: Insert [owned workflow footage] at the use point, label stages, and end with [CTA].
Replaceable variables: [audience], [platform], [avatar], [routine task], [product], [verified handoff], [owned workflow footage], [CTA].
Production note: Film real product operation as a separate asset.
Success check:
- Does the product enter at a believable point?
- Does the B-roll show the actual use?
10. Frequently Asked Question Ad
Best for: One decision-stage question about fit or compatibility.
Concept: Answer one frequent question before adding context. The avatar should repeat only enough of the question to orient the viewer, then give a verified answer, one caveat, and one next step. Pair the response with a single proof asset. Do not turn the card into a rapid list of loosely related questions.
Video structure: Question → direct answer → condition → detail page.
Prompt — copy-ready input pack:
- Setup: Produce a 10-second FAQ host clip for [audience], planned for 9:16 [platform], in a front-facing close-up.
- Spoken script/audio brief: Answer [approved question] with [verified answer] in the first line. Add [important condition], then direct viewers to [CTA].
- Action/expression prompt: Nod on [verified answer], soften the expression on [important condition], then hold eye contact. Preserve the close-up, background, and light direction.
- Edit/CTA cue: Show [approved question] above [proof asset], caption the condition, and finish with [CTA].
Replaceable variables: [audience], [platform], [approved question], [verified answer], [important condition], [proof asset], [CTA].
Production note: Check the answer and condition immediately before publication.
Success check:
- Does the answer appear in the first line?
- Does the proof address that single question?
11. Permissioned Comment Reply
Best for: An approved comment or clearly labeled representative question.
Concept: Show an anonymized, permissioned comment or label the wording as representative before the avatar responds. The presenter should address the question, not imitate the commenter or imply a private relationship. Use a source label and remove personal data. This format turns audience language into a useful explanation while keeping consent and identity boundaries visible.
Video structure: Labeled comment → acknowledgment → sourced answer → resource.
Prompt — copy-ready input pack:
- Setup: Create a 10-second brand-reply clip for [audience], planned for 9:16 [platform], with [avatar] beside a comment area.
- Spoken script/audio brief: Acknowledge [comment], answer with [verified information], and invite viewers to [CTA]. Do not name the commenter.
- Action/expression prompt: Look toward [comment], return to camera, nod after [verified information], then end neutral. Keep the crop, comment area, and lighting fixed.
- Edit/CTA cue: Add the anonymized comment with [permission label], cite [answer source], and close with [CTA].
Replaceable variables: [audience], [platform], [avatar], [comment], [verified information], [permission label], [answer source], [CTA].
Production note: Store permission and remove unauthorized personal details.
Success check:
- Is the comment permissioned or labeled representative?
- Does the answer match the cited source?
12. Guided Product Demonstration
Best for: Framing a real product operation with a short host.
Concept: Let the avatar set the task, then cut to owned footage showing the product doing it. The presenter can explain what viewers should watch but should not appear to operate an object or interface it never touched. Return to the host for one takeaway and next step. The demonstration must match the spoken claim exactly.
Video structure: Task → owned demonstration → observable detail → takeaway.
Prompt — copy-ready input pack:
- Setup: Generate a 10-second demo-guide for [audience], targeting 16:9 [platform], with [avatar] beside edit space.
- Spoken script/audio brief: Introduce [demo task], ask viewers to watch [observable detail], state [verified takeaway], then point to [CTA].
- Action/expression prompt: Glance toward the demo area, nod on [verified takeaway], then close centered. Hold the host position, background, and lighting steady.
- Edit/CTA cue: Insert [owned demo footage] between lines, add one pointer label, and finish with [CTA].
Replaceable variables: [audience], [platform], [avatar], [demo task], [observable detail], [verified takeaway], [owned demo footage], [CTA].
Production note: Preserve the real product sequence in the cutaway.
Success check:
- Does the footage show the stated task?
- Does the avatar only frame the demonstration?
13. Approved Brand Origin Story
Best for: Explaining brand origins from approved records and assets.
Concept: Use a fictional brand narrator to connect an approved problem context, a documented company decision, and the current mission. Support the timeline with licensed archive images, dated records, or owned visuals. The avatar must not speak as the founder or claim memories. Keep the story factual and tied to the intended audience today.
Video structure: Problem context → documented decision → mission → full story.
Prompt — copy-ready input pack:
- Setup: Create a 20-second fictional brand-narrator clip for [audience], planned for 16:9 [platform], using [avatar] against a stable background.
- Spoken script/audio brief: Describe [context], state [decision/date], connect it to [mission], then invite viewers to [CTA].
- Action/expression prompt: Lift the brows at [decision/date], nod on [mission], then finish calmly. Preserve the frame, backdrop, and light level.
- Edit/CTA cue: Add [archive] and [record] beside matching lines, then close with [CTA].
Replaceable variables: [audience], [platform], [avatar], [context], [decision/date], [mission], [archive], [record], [CTA].
Production note: Have the owner approve every date, event, and asset.
Success check:
- Is the presenter clearly a fictional narrator?
- Can every detail be traced to a record?
14. Feature-to-Benefit Ad
Best for: Connecting one verified feature to one user task.
Concept: Start with a current feature fact, then translate it into a practical use for a defined audience. Keep feature and benefit separate: the feature describes what the product does, while the benefit explains why that may matter for one task. Add real product footage so viewers can inspect the function instead of trusting the presenter alone.
Video structure: Verified feature → documented function → task benefit → details.
Prompt — copy-ready input pack:
- Setup: Make a 10-second feature guide for [audience], planned for 9:16 [platform], with [avatar] in a medium close-up.
- Spoken script/audio brief: State [feature] and its [function]. Explain how it may help [task], then invite viewers to [CTA].
- Action/expression prompt: Lift the brows on [feature], nod on [task], then end neutral. Keep the crop, background, and exposure unchanged.
- Edit/CTA cue: Show [current product footage] during the function line, add a source note, and end with [CTA].
Replaceable variables: [audience], [platform], [avatar], [feature], [function], [task], [current product footage], [CTA].
Production note: Verify the feature name, function, and current availability.
Success check:
- Are feature and benefit stated separately?
- Does the footage show the documented function?
15. Verified Offer and CTA Ad
Best for: A current, owner-approved offer with clear eligibility and timing.
Concept: Use a disclosed brand presenter to state who qualifies, what the approved offer includes, when it ends, and what action to take. Keep precise wording aligned with the owner-supplied terms. Add a dated end card during editing. Do not invent urgency, scarcity, pricing, savings, or availability beyond the approved source.
Video structure: Eligibility → exact offer → deadline → one action.
Prompt — copy-ready input pack:
- Setup: Produce a 10-second offer presenter for [audience], planned for 9:16 [platform], using [avatar] in a front-facing close-up.
- Spoken script/audio brief: State [approved offer], [eligibility], and [verified deadline with time zone]. Tell viewers to [CTA].
- Action/expression prompt: Nod after [eligibility], hold the gaze through [verified deadline with time zone], then close. Hold the close-up, backdrop, and lighting steady.
- Edit/CTA cue: Build a dated end card with [terms source], [deadline], [qualifier], and one [CTA].
Replaceable variables: [audience], [platform], [avatar], [approved offer], [eligibility], [verified deadline with time zone], [terms source], [deadline], [qualifier], [CTA].
Production note: Recheck the offer fields immediately before publication.
Success check:
- Do the script and end card match the source?
- Are eligibility and deadline unambiguous?
10 Ways to Pair a Talking Avatar With Product B-Roll
Talking Avatar gives you presenter footage, not a finished multi-shot ad. Generate the host clip first, collect owned or approved product footage, then build these layouts in an external editor. Each timeline below covers the entire final runtime. Treat timestamps as edit decisions, not controls inside the action prompt.
16. Avatar Hook → Full-Screen Product Demo
Best for: Reels and Shorts requiring visual proof before action.
Concept: Open with a five-second avatar line that names the task, then give the product the full frame. Use this layout when footage proves the message better than more explanation. The host sets one viewing question; the demonstration answers it. End on the product and one next action, not another presenter section.
Video structure: 0–5s: Avatar hook. 5–8s: Starting state. 8–17s: Owned demonstration. 17–20s: Verified result and CTA.
Prompt — copy-ready input pack:
- Setup: 20-second 9:16 delivery; a calm guide addresses [audience] about [task].
- Spoken script/audio brief: Explain how [footage] proves [verified benefit] in a direct, factual tone.
- Action/expression prompt: Hold eye contact, lift the brows briefly on [verified benefit], then nod once.
- Edit/CTA cue: Cut to [footage] at five seconds; end with [CTA].
Replaceable variables: [audience], [task], [verified benefit], [footage], [CTA]
Production note: Assemble externally. Talking Avatar creates the presenter clip; it neither generates nor cuts B-roll.
Success check:
- Does the demonstration answer the opening question?
- Do all claims match the footage?
17. Split-Screen Avatar and Product
Best for: Product and social clips keeping explanation and evidence visible together.
Concept: Keep the avatar on one side and product footage on the other, so viewers connect each line with matching evidence. Hold both panels steady and give the product one clear task. Reserve caption-safe space. Remove decorative overlays that compete with the face, product, or proof. Keep the full frame easy to scan.
Video structure: 0–4s: Question. 4–11s: First detail. 11–17s: Demonstrated action. 17–20s: CTA in reserved space.
Prompt — copy-ready input pack:
- Setup: 20-second 9:16 delivery; a helpful presenter addresses [viewer] from the left panel.
- Spoken script/audio brief: Explain [product task] and match each line to right-side [evidence] in a neutral tone.
- Action/expression prompt: Keep eye contact, tilt the head slightly before the key detail, then close with a restrained smile.
- Edit/CTA cue: Build the split screen externally; reserve space for [caption] and finish with [CTA].
Replaceable variables: [viewer], [product task], [evidence], [caption], [CTA]
Production note: Combine clips externally; Talking Avatar creates neither product footage nor the layout.
Success check:
- Are the face, caption, and product clear?
- Does each line match adjacent footage?
18. Picture-in-Picture Presenter
Best for: Software demos where the screen must remain primary.
Concept: Let the demonstration fill the frame while a small avatar guides from one corner. This works when viewers need continuous access to the interface or product action. The presenter adds orientation instead of repeating the footage. Choose a corner that never covers controls, labels, hands, measurements, or the final success state.
Video structure: 0–3s: Picture-in-picture introduction. 3–13s: Continuous task footage. 13–17s: Success state. 17–20s: Next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a concise guide appears at [overlay corner] for [user].
- Spoken script/audio brief: Explain [task], name [visible step], and confirm success in a measured tone.
- Action/expression prompt: Maintain a relaxed gaze, add one small nod after the instruction, then hold a neutral expression.
- Edit/CTA cue: Composite externally, keep active controls clear, and finish with [next step].
Replaceable variables: [user], [task], [visible step], [overlay corner], [next step]
Production note: Use Screen Keying, then composite externally; Talking Avatar creates no evidence.
Success check:
- Does the presenter avoid active details?
- Is the success state clear?
19. Avatar Commentary Over Product Footage
Best for: Product stories needing a host and visual evidence.
Concept: Start on the avatar, carry the narration across full-screen product footage, then return for the close. The continuous voice keeps the message coherent while visuals change. Unlike picture-in-picture, the host disappears during the central evidence section. Every spoken point there needs a specific, approved matching shot. Keep the timeline easy to audit.
Video structure: 0–4s: Context. 4–6s: Transition. 6–15s: Narrated footage. 15–18s: Takeaway. 18–20s: CTA.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a narrator frames [story] at the opening and closing.
- Spoken script/audio brief: Explain [visible moments] conversationally, then close on [takeaway].
- Action/expression prompt: Begin with calm eye contact, soften the brow at [takeaway], then nod once.
- Edit/CTA cue: Run narration under [B-roll], then return to the avatar for [CTA].
Replaceable variables: [story], [visible moments], [takeaway], [B-roll], [CTA]
Production note: Edit externally; Talking Avatar supplies the host clip, not B-roll or the sequence.
Success check:
- Does every narration point match footage?
- Does the return add a takeaway?
20. Alternating Talking Head and Product Close-Ups
Best for: Consideration videos combining explanation with close product inspection.
Concept: Alternate between the avatar and product close-ups only when the information changes. Use the presenter to frame meaning, then show the exact texture, control, component, or result. Return to the host for interpretation, not repetition. Each shot gets one clear job, so the sequence avoids mechanical cuts at equal intervals.
Video structure: 0–4s: Host framing. 4–8s: First close-up. 8–12s: Host interpretation. 12–17s: Demonstration close-up. 17–20s: CTA.
Prompt — copy-ready input pack:
- Setup: 20-second 9:16 delivery; an informed guide addresses [viewer] in two presenter sections.
- Spoken script/audio brief: Explain [product details] and their [relevance] without promising a result.
- Action/expression prompt: Hold eye contact, shift the gaze briefly before the second point, then settle into a neutral close.
- Edit/CTA cue: Cut on information changes, match [close-ups] to their lines, and finish with [CTA].
Replaceable variables: [viewer], [product details], [relevance], [close-ups], [CTA]
Production note: Edit externally; Talking Avatar neither captures close-ups nor sets the rhythm.
Success check:
- Does every cut mark a topic change?
- Are both details easy to inspect?
21. Step-by-Step Product Walkthrough
Best for: Help centers and onboarding tutorials teaching one short task.
Concept: Break one task into three visible steps and match each instruction to the current product state. The avatar can introduce the goal and provide narration, but the walkthrough needs real screen recording or owned product footage. Keep labels exact, show the result after each action, and stop once the viewer reaches the first successful outcome.
Video structure: 0–4s: Goal. 4–8s: Step one. 8–13s: Step two. 13–18s: Step three and success. 18–20s: Next action.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a patient instructor guides [user] through [three steps].
- Spoken script/audio brief: Explain [task] using approved labels and visible confirmations.
- Action/expression prompt: Keep steady eye contact, nod once after the goal, then smile slightly at success.
- Edit/CTA cue: Match each instruction to exact footage, show [success state], then give [next action].
Replaceable variables: [user], [task], [three steps], [success state], [next action]
Production note: Record the workflow and edit externally; Talking Avatar does not create or synchronize walkthrough footage.
Success check:
- Does each instruction match the visible state?
- Can viewers finish without a missing step?
22. Before-and-After Layout
Best for: Case studies and tutorials comparing two documented states.
Concept: Use the avatar to explain how to read a before-and-after comparison, not to invent the improvement. Present both approved states at the same scale with clear external labels. Name the process, condition, or time difference that separates them. This card defines the layout only; the evidence and claim standard must come from the source material.
Video structure: 0–4s: Comparison. 4–8s: Labeled before. 8–12s: Condition note. 12–17s: Matched after. 17–20s: Takeaway.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a neutral narrator introduces [before] and [after].
- Spoken script/audio brief: Explain [condition], what remained [constant], and how to read the comparison without unsupported causation.
- Action/expression prompt: Keep a level gaze, lift the brows slightly before the distinction, then close neutrally.
- Edit/CTA cue: Match both frames externally, add [source labels], and finish with [takeaway].
Replaceable variables: [before], [after], [condition], [constant], [source labels], [takeaway]
Production note: Build and label both states externally; Talking Avatar creates neither evidence nor the layout.
Success check:
- Are both states sourced and equally framed?
- Is unsupported causation absent?
23. Side-by-Side Comparison Layout
Best for: Buying guides comparing two options under shared criteria.
Concept: Build two parallel columns and let the avatar explain how to scan them. Apply the same criteria, units, scale, and evidence standard to both options. Keep the language neutral and show trade-offs rather than declaring a universal winner. This layout supports a fair decision canvas; it does not supply the argument or comparison data.
Video structure: 0–4s: Need. 4–9s: Criterion one. 9–14s: Criterion two. 14–18s: Trade-offs. 18–20s: Next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a neutral guide frames [need] and introduces [options].
- Spoken script/audio brief: Compare [two criteria] and explain [trade-offs] without attack language.
- Action/expression prompt: Hold calm eye contact, tilt the head slightly before trade-offs, then nod once.
- Edit/CTA cue: Build equal columns externally, keep labels readable, and end with [next step].
Replaceable variables: [need], [options], [two criteria], [trade-offs], [next step]
Production note: Source the data and edit externally; Talking Avatar creates neither comparison evidence nor the layout.
Success check:
- Do both options use identical criteria and units?
- Does each option get a fair limitation?
24. Proof Cutaway Layout
Best for: Explainers requiring immediate proof for one approved statement.
Concept: Place a proof cutaway directly after the statement it supports. The evidence may be an owned demonstration, current interface capture, cited source card, or approved measurement. Return to the avatar only to interpret what viewers just saw. Avoid generic lifestyle footage; the cutaway must address the exact preceding words and remain readable long enough to inspect.
Video structure: 0–4s: Verified point. 4–6s: Source label. 6–13s: Proof. 13–17s: Interpretation. 17–20s: Next step.
Prompt — copy-ready input pack:
- Setup: 20-second 9:16 delivery; an evidence-led presenter states [fact] before one cutaway.
- Spoken script/audio brief: Name [inspection point] and explain only [conclusion] supported by [evidence].
- Action/expression prompt: Keep direct eye contact, lift the brows briefly before proof, then give one restrained nod.
- Edit/CTA cue: Insert the proof after the claim, add [source label], and end with [action].
Replaceable variables: [fact], [evidence], [inspection point], [conclusion], [source label], [action]
Production note: Insert verified proof externally; Talking Avatar creates neither evidence nor the cutaway sequence.
Success check:
- Does the cutaway prove the exact preceding point?
- Is its source or measurement readable?
25. Avatar CTA Over Product End Card
Best for: Short ads needing one action and readable terms.
Concept: Reserve the final five seconds for a clean product end card with a small avatar beside it. The presenter should recap one supported value, then state one action. Keep the product name, required terms, and CTA readable. This layout works best when the closing pose stays still enough for viewers to scan the card before the edit ends.
Video structure: 0–5s: Recap. 5–10s: Proof. 10–12s: Transition. 12–15s: Avatar, identity, terms, and CTA.
Prompt — copy-ready input pack:
- Setup: 15-second 9:16 delivery; use [layout] for a separate five-second avatar close.
- Spoken script/audio brief: Recap [value], then state [CTA] in a calm tone.
- Action/expression prompt: Hold eye contact, nod once after [value], then keep a soft closing smile.
- Edit/CTA cue: Key the avatar beside [product identity] externally; reserve readable space for [terms].
Replaceable variables: [value], [product identity], [terms], [CTA], [layout]
Production note: Use Screen Keying, then edit externally; Talking Avatar creates neither card nor composite.
Success check:
- Is there only one action?
- Are identity and terms readable to the end?
10 AI Tutor and Virtual Instructor Video Ideas
Use a talking avatar as the guide, not the entire lesson. Each idea starts with one learning objective and gives the learner something to say, choose, or do. Build longer lessons from separate 10- or 20-second presenter segments. Then add current slides, demonstrations, or screen recordings in the edit.
26. Microlearning Lesson
Best for: Mobile learning, course refreshers, and one-skill workplace training.
Concept: Teach one action that a learner can complete immediately. State the learning objective, demonstrate one example, and reserve a pause for practice. This format differs from a recap because it introduces a new skill instead of reviewing prior material. If the explanation needs more room, generate separate 10- or 20-second presenter segments and place the example between them.
Video structure: Outcome → worked example → learner practice → answer check.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 16:9 plan, microlearning guide for
[learner group]. - Spoken script/audio brief: Teach
[single skill], show one example, then ask learners to complete[small action]. - Action/expression prompt: Maintain eye contact, nod after the objective, and stay still during practice.
- Edit/CTA cue: Add an example slide and pause cue; end with a practice reminder.
Replaceable variables: [learner group] [single skill] [small action]
Production note: Verify the slide, and join longer lessons from separate clips before the lesson goes live.
Success check:
- Can the learner perform the stated outcome?
- Is the practice pause long enough?
27. Language Pronunciation Coach
Best for: Language apps, pronunciation drills, and short speaking-practice posts.
Concept: Give the learner a clean model, one visible sound cue, and enough silence to repeat it. The lesson objective is to pronounce [word or phrase] with the intended stress or rhythm. Unlike a vocabulary definition, this card centers on listening and speaking. Keep the avatar's mouth visible and use a permitted voice that suits the target language.
Video structure: Phrase → slow model → stress cue → two repeat windows.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 9:16 plan, front-facing coach for
[language level]. - Spoken script/audio brief: Say
[word or phrase]naturally, then slowly. Explain[stress cue]and leave two repeat gaps. - Action/expression prompt: Keep the mouth visible, lift the brows on the stressed sound, then nod once.
- Edit/CTA cue: Add approved spelling and stress marks; end with a repeat cue.
Replaceable variables: [language level] [word or phrase] [stress cue]
Production note: A qualified speaker must review the audio, caption, and pronunciation.
Success check:
- Are both repeat windows long enough?
- Does a qualified reviewer approve the pronunciation?
28. Software Walkthrough Instructor
Best for: Help centers, user onboarding, and in-product learning libraries.
Concept: Guide one current software task while a real screen recording supplies the evidence. The learning objective is to complete [task], and the learner action is to pause and perform the same clicks. This differs from a feature explainer because success depends on finishing a task. Use exact interface labels and avoid asking the avatar to generate or imitate the product screen.
Video structure: Task → current screen steps → learner attempt → visible success state.
Prompt — copy-ready input pack:
- Setup: Two 20-second 16:9 clips, software instructor for
[user type]. - Spoken script/audio brief: Explain
[task], name current UI labels, and cue the learner to pause and try it. - Action/expression prompt: Face forward, glance toward the screen once, nod, then return to neutral.
- Edit/CTA cue: Insert current screen capture after each instruction; end on
[success state].
Replaceable variables: [user type] [task] [success state]
Production note: Record the current interface and obtain product-owner approval.
Success check:
- Does each instruction match the visible interface?
- Can a new user reach the success state?
29. Worked Example Lesson
Best for: Math, coding, finance basics, and process-based course modules.
Concept: Reveal how an answer is built instead of presenting only the result. The learning objective is to apply [method] to [example problem]. Ask the learner to predict the next operation before each reveal. This pattern works best with a board or slide added in the edit. Split the reasoning into 10- or 20-second clips so the narration never races ahead of the visual.
Video structure: Given facts → prediction → operations → traced conclusion.
Prompt — copy-ready input pack:
- Setup: Three 20-second 16:9 clips, patient instructor for
[learner level]. - Spoken script/audio brief: Solve
[example problem]with[method]. Explain each step and ask for one prediction before the final operation. - Action/expression prompt: Maintain eye contact, nod after conclusions, and stay still during prediction pauses.
- Edit/CTA cue: Reveal approved board steps in sequence; end with a parallel practice item.
Replaceable variables: [learner level] [example problem] [method]
Production note: Verify every operation against the approved course source.
Success check:
- Can the learner explain each step?
- Does the answer trace back to the given facts?
30. Quiz Answer Explanation
Best for: Assessment feedback, exam review, and interactive lesson posts.
Concept: Turn one quiz item into a short reasoning exercise. The learning objective is to distinguish the correct principle from two plausible mistakes. First ask the learner to commit to an answer. Then explain why the correct choice works and why each distractor fails for a different reason. This goes beyond an answer reveal by teaching a reusable decision rule.
Video structure: Question → learner choice → answer reveal → reasons.
Prompt — copy-ready input pack:
- Setup: Two 20-second 9:16 clips, quiz coach for
[learner group]. - Spoken script/audio brief: Ask
[question], pause, then identify the correct option within[choices]and explain each distractor. - Action/expression prompt: Stay attentive during the pause, nod on reveal, and avoid celebration.
- Edit/CTA cue: Show approved answer cards; end with
[transfer question].
Replaceable variables: [learner group] [question] [choices] [transfer question]
Production note: The subject owner must verify every answer and rationale before the lesson goes live.
Success check:
- Does each distractor get a distinct reason?
- Can the learner answer the transfer question?
31. Scenario-Based Training
Best for: Reviewed customer-service, workplace, and safety decision practice.
Concept: Place the learner at one decision point with enough context to choose an approved response. The learning objective is to select that response when [scenario condition] occurs. Ask the learner to choose before the presenter explains the consequence. This format teaches judgment, not memorization. Use fictional people and remove customer, employee, or incident details that could identify anyone.
Video structure: Situation → two choices → learner decision → approved response and escalation.
Prompt — copy-ready input pack:
- Setup: Two 20-second 16:9 clips, training facilitator for
[learner role]. - Spoken script/audio brief: Describe
[scenario condition]without personal data. Present[choices], then explain the approved response. - Action/expression prompt: Stay calm and still during the choice, then nod once.
- Edit/CTA cue: Add reviewed scenario cards; end with
[escalation route].
Replaceable variables: [learner role] [scenario condition] [choices] [escalation route]
Production note: High-stakes scenarios require authoritative sources, policy-owner approval, and human review before any learner sees them.
Success check:
- Does the learner choose before the explanation?
- Does the response match the source and escalation route?
32. Lesson Recap and Summary
Best for: Module endings, spaced review, and pre-assessment refreshers.
Concept: Use retrieval prompts to help learners rebuild the lesson from memory. The learning objective is to recall and connect [three key ideas]. Ask one short question for each idea before showing a summary card. This differs from microlearning because it checks prior knowledge rather than introducing a new skill. End with a next activity that uses the recalled information.
Video structure: Recall goal → three prompts → response pauses → summary and next activity.
Prompt — copy-ready input pack:
- Setup: Two 20-second 16:9 clips, recap host for
[course audience]. - Spoken script/audio brief: Prompt recall of
[three key ideas], leave response gaps, then connect them to[next activity]. - Action/expression prompt: Stay focused for each question, still during pauses, then nod once.
- Edit/CTA cue: Reveal each approved answer after its pause; end on the next activity.
Replaceable variables: [course audience] [three key ideas] [next activity]
Production note: Keep answers hidden and add clips if the pace feels rushed.
Success check:
- Does recall happen before each answer?
- Does the next activity reuse all three ideas?
33. Employee Onboarding Presenter
Best for: New-hire portals, team handoffs, and verified process orientation.
Concept: Orient a new employee to one workflow, its owner, and the first required action. The learning objective is to route the triggering request correctly. Ask the learner to identify the owner and next step before the answer appears. This stays narrower than a welcome video and avoids pretending the avatar is a real employee. Use a disclosed training presenter and approved role-level information only.
Video structure: Workflow purpose → trigger → owner question → approved handoff.
Prompt — copy-ready input pack:
- Setup: Two 20-second 16:9 clips, disclosed onboarding presenter for
[new-hire group]. - Spoken script/audio brief: Explain when
[workflow]starts, what to provide, who owns the next step, and where to find the procedure. - Action/expression prompt: Welcome viewers, nod after the purpose, and stay still during the question.
- Edit/CTA cue: Add an approved workflow card; end with
[procedure destination].
Replaceable variables: [new-hire group] [workflow] [procedure destination]
Production note: Obtain process-owner approval and exclude private employee data.
Success check:
- Can the learner name the owner and next action?
- Does the workflow match the current procedure?
34. Safety and Compliance Instructor
Best for: Approved procedure refreshers and mandatory training support.
Concept: Teach one required response from an authoritative, current source. The learning objective is to recognize [condition] and take [required action]. Ask the learner to state the action before the presenter reveals it. Keep this card literal and narrow. It must never replace formal training, professional advice, or an organization's required instruction and assessment process.
Video structure: Source and scope → condition → learner response → action and escalation.
Prompt — copy-ready input pack:
- Setup: Two 20-second 16:9 clips, compliance instructor for
[authorized audience]. - Spoken script/audio brief: Use approved wording for
[condition],[required action], and[escalation point]. Direct learners to the full procedure. - Action/expression prompt: Keep a serious gaze, avoid broad gestures, pause fully, and close neutrally.
- Edit/CTA cue: Show the source and revision date; end with the official procedure destination.
Replaceable variables: [authorized audience] [condition] [required action] [escalation point]
Production note: Require authoritative sources, subject review, human approval, and update monitoring.
Success check:
- Does required wording match the approved source?
- Is the escalation point unambiguous?
35. Permission-Safe Course Introduction
Best for: Course welcomes and learning paths.
Concept: Welcome learners by permitted cohort and clearly point them to the correct first module. The objective is to find [starting module] and complete [first action]. Use only approved group-level context. Never place names, performance history, or sensitive records in the prompt. Present the host only as a disclosed course guide.
Video structure: Welcome → route → first action.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 16:9, course guide for
[approved cohort]. - Spoken script/audio brief: Welcome learners; state
[course outcomes], point to[starting module], and request[first action]. - Action/expression prompt: Smile, nod after the outcomes, and close neutrally.
- Edit/CTA cue: Show the approved map and starting instruction.
Replaceable variables: [approved cohort] [course outcomes] [starting module] [first action]
Production note: Use permitted cohort data with course-owner approval.
Success check:
- Can learners find the starting module?
- Does the clip exclude sensitive data?
8 Product Demo and Explainer Video Ideas
These ideas focus on one real product task at a time. The avatar introduces or explains the task, while current screen recordings, approved release notes, or owned product footage provide the evidence. Keep interface labels and product steps current. If a fact, date, claim, or availability detail lacks an approved source, leave it out.
36. SaaS Feature Explainer
Best for: Help centers, product blogs, and social feature education.
Concept: Frame the feature around the job it performs, not a list of interface details. Start with the user problem, show the exact current action, then explain the supported result. One interface state is enough. This keeps the video useful when the audience needs to understand where the feature fits before trying it.
Video structure: User problem → current interface → feature action → supported result → approved next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a product guide explains [feature] for [problem].
- Spoken script/audio brief: Describe [action] and [result] using the current [UI label].
- Action/expression prompt: Hold eye contact, glance toward the screen area, then nod once with relaxed shoulders.
- Edit/CTA cue: Show the exact action in a current capture; finish with [next step].
Replaceable variables: [problem], [feature], [UI label], [action], [result], [next step]
Production note: Record the current interface, verify its labels, and add the capture and captions externally.
Success check:
- Does it explain one feature job?
- Does the visible action match the current interface?
37. Mobile App Onboarding Video
Best for: In-app help and tutorials guiding a user's first success.
Concept: Choose one activation task and remove everything that does not help the user finish it. Show the starting screen, each required tap, and the visible confirmation. The avatar gives context and reassurance while the phone recording carries the instruction. Stop after the first success instead of touring menus the viewer does not yet need.
Video structure: First goal → starting screen → required taps → confirmation → optional next action.
Prompt — copy-ready input pack:
- Setup: 20-second 9:16 delivery; a concise guide supports [user] with [task].
- Spoken script/audio brief: Move from [starting screen] through [taps], naming only current labels.
- Action/expression prompt: Hold a welcoming gaze, nod once after the goal, then smile slightly at confirmation.
- Edit/CTA cue: Match each line to current footage, show [confirmation], then offer [next action].
Replaceable variables: [user], [task], [starting screen], [taps], [confirmation], [next action]
Production note: Use permission-safe current footage; add tap indicators, captions, and the avatar externally.
Success check:
- Can a new user repeat every visible tap?
- Does it end at the first success?
38. Ecommerce Product How-To
Best for: Product pages and support clips teaching setup, use, or care.
Concept: Teach one physical task with owned footage and instructions from an approved manual or product expert. The avatar introduces the goal and narrates safety or care notes. The product footage must show hand placement, part orientation, and the final check clearly. Do not ask the avatar to hold or operate a product that is not present in its source clip.
Video structure: Task → required parts → approved sequence → final check → care or safety reminder.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a neutral instructor introduces [task] for [audience].
- Spoken script/audio brief: Explain [steps], [parts], and [final check] without adding performance claims.
- Action/expression prompt: Keep eye contact, lower the chin before the safety note, then close neutrally.
- Edit/CTA cue: Match every step to owned close-up footage; end with [reminder].
Replaceable variables: [audience], [task], [parts], [steps], [final check], [reminder]
Production note: Confirm the current manual, film separately, and assemble the footage and labels externally.
Success check:
- Does the footage show each required physical step?
- Does the reminder match an approved source?
39. Neutral Product Comparison Explainer
Best for: Buying guides helping viewers choose between two solution types.
Concept: Start with the viewer's need, then compare two options under the same verified criteria. Explain where each option fits and where it may not. The avatar acts as a decision guide, while an external comparison canvas shows the evidence. Avoid a universal winner unless the data supports one for the stated use case.
Video structure: Need → both options → shared criteria → one trade-off each → fit-based next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a neutral advisor frames [need] and [options].
- Spoken script/audio brief: Compare [criteria], giving balanced [strengths] and [limitations].
- Action/expression prompt: Keep an even expression, tilt the head slightly before trade-offs, then nod once.
- Edit/CTA cue: Show an equal comparison table externally; end with [question].
Replaceable variables: [need], [options], [criteria], [strengths], [limitations], [question]
Production note: Verify every point with equal evidence; build the table and labels externally.
Success check:
- Are the criteria identical for both options?
- Does the conclusion avoid attacking either option?
40. Verified New Feature Announcement
Best for: Release notes and dated updates about one approved change.
Concept: Treat a feature announcement as a dated explanation, not a teaser. State what changed, who can access it, and one current way to use it. Show the exact interface label or approved product view. If availability varies by plan, region, platform, or rollout stage, say so only from the release source.
Video structure: Release and date → change → current action → verified availability → next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; an update host presents [feature] to [user].
- Spoken script/audio brief: State [date], [change], and [availability] in an informative, time-specific tone.
- Action/expression prompt: Hold eye contact, lift the brows slightly on the change, then nod once.
- Edit/CTA cue: Insert the current product view, display the date, and finish with [next action].
Replaceable variables: [feature], [date], [change], [user], [availability], [next action]
Production note: Use the approved release note and capture; have a product owner review the final edit.
Success check:
- Do the date, label, and availability match the release source?
- Is the use free of unsupported promises?
41. Product FAQ Explainer
Best for: Support pages answering one recurring post-purchase usage question.
Concept: Answer the question in the first sentence, then show the smallest procedure or evidence that confirms the answer. Keep this focused on use after purchase, not pricing, fit, or another sales objection. The avatar provides the explanation, while a current screen or owned product clip lets the viewer verify the result.
Video structure: Usage question → direct answer → required action → visible result → support resource.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a support guide answers [question].
- Spoken script/audio brief: Lead with [answer], explain [procedure], and name [confirmation] in a patient tone.
- Action/expression prompt: Keep a calm gaze, nod once after the answer, then soften at confirmation.
- Edit/CTA cue: Match the procedure to [footage]; end with [support destination].
Replaceable variables: [question], [answer], [procedure], [confirmation], [footage], [support destination]
Production note: Check current help content; add the question card, evidence, captions, and link externally.
Success check:
- Does the first sentence answer directly?
- Can viewers confirm the result from the footage?
42. Troubleshooting Guide
Best for: Help centers diagnosing one low-risk symptom with a reversible test.
Concept: Name the symptom exactly, give one likely documented cause, and show the smallest safe test. Then define what result means the viewer should stop and escalate. The avatar keeps the diagnosis orderly, while current screen or product footage shows the check. Do not improvise causes or compress a high-stakes procedure into a short clip.
Video structure: Symptom → documented cause → reversible test → result → escalation point.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a calm guide addresses [symptom] and [cause].
- Spoken script/audio brief: Explain [test], expected [result], and [escalation trigger] using approved support guidance.
- Action/expression prompt: Hold a focused gaze, tighten the brows slightly at the warning, then close neutrally.
- Edit/CTA cue: Show the test and result externally; end with [support route].
Replaceable variables: [symptom], [cause], [test], [result], [escalation trigger], [support route]
Production note: Use current support documentation and owner review; send high-stakes topics to a qualified human.
Success check:
- Is the first test safe, reversible, and source-backed?
- Is the escalation condition explicit?
43. Permission-Safe Sales Introduction
Best for: Account outreach using approved context and one respectful next step.
Concept: Personalize around an approved role, company need, or public business priority. Do not use sensitive data, private behavior, or fake familiarity. The avatar should explain why the message may be relevant, offer one verified product fit, and invite one action. Keep the wording easy to update when the account context changes.
Video structure: Approved context → relevant need → verified fit → boundary → next step.
Prompt — copy-ready input pack:
- Setup: 20-second 16:9 delivery; a disclosed representative addresses [audience] using [context].
- Spoken script/audio brief: State [need], explain [verified fit], and acknowledge [boundary] without fake familiarity.
- Action/expression prompt: Keep open eye contact, nod once after the fit, then finish with a calm smile.
- Edit/CTA cue: Add the approved context card externally; end with [next action].
Replaceable variables: [audience], [context], [need], [verified fit], [boundary], [next action]
Production note: Approve all context and assets, remove sensitive data, add required AI disclosure, and review externally.
Success check:
- Is every personalized detail approved and non-sensitive?
- Does it avoid fake familiarity or experience?
7 Social Media and Creator Video Ideas
Recurring avatars work best when viewers recognize the format before the topic. Each idea fixes an episode pattern, cadence, and changing content slot. Keep presenter sections short, support dated claims, and edit the avatar around the material viewers came to see.
44. Faceless YouTube Host
Best for: Tutorials, commentary channels, and chaptered YouTube videos.
Concept: Use the avatar as a recurring navigator rather than an uninterrupted narrator. Publish the same 10-second opening, short chapter bridges, and closing handoff structure in every upload. The topic and supporting footage change, but the host's role stays fixed. This gives a faceless channel a recognizable presence while leaving most screen time for demonstrations, sources, interviews, or examples.
Video structure: Episode question → first visual → chapter bridges → next-video handoff.
Prompt — copy-ready input pack:
- Setup: Separate 10-second 16:9 clips, YouTube host for
[channel audience]. - Spoken script/audio brief: Introduce
[episode question], preview[supporting material], and hand viewers into each chapter in a consistent tone. - Action/expression prompt: Maintain eye contact, nod on each handoff, and use one neutral closing pose.
- Edit/CTA cue: Cut to the promised visual; close with
[next action].
Replaceable variables: [channel audience] [episode question] [supporting material] [next action]
Production note: Use permitted host assets and assemble the full video externally.
Success check:
- Does each host segment hand off within 10 seconds?
- Does the format stay consistent across uploads?
45. Daily Tips Series
Best for: Daily Shorts, Reels, TikTok posts, and community learning feeds.
Concept: Build a repeatable series around one tiny action per episode. Use the same four beats every day: a problem cue, one tip, a quick viewer action, and a fixed sign-off. Limit each 30-day run to [topic boundary] so the series does not drift into unrelated advice. Change only the tip and example when testing which episode framing viewers understand best.
Video structure: Problem cue → one tip → viewer action → fixed sign-off.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 9:16 plan, tips host for
[audience]within[topic boundary]; publish[cadence]. - Spoken script/audio brief: Frame today's problem, teach
[single tip], and ask viewers to try[micro-action]. - Action/expression prompt: Start attentive, nod after the tip, and hold a friendly closing pose.
- Edit/CTA cue: Add one example and episode number; end with
[sign-off].
Replaceable variables: [audience] [cadence] [single tip] [micro-action] [sign-off] [topic boundary]
Production note: Verify each tip; high-stakes advice requires qualified human review.
Success check:
- Does the episode teach one action?
- Do cadence and sign-off match the series?
46. Sourced Weekly News or Industry Recap
Best for: Weekly creator briefings, company channels, and niche industry feeds.
Concept: Summarize dated sources on a fixed weekly schedule. Keep the edition to three verified items, then explain why each matters to [audience]. The avatar organizes the recap; it does not invent reporting or imply firsthand access. Use a stable headline, context, and source-card pattern. Remove or replace any clip when an update becomes false or materially incomplete.
Video structure: Coverage dates → three sourced items → audience impact → full source list.
Prompt — copy-ready input pack:
- Setup: Three 20-second 9:16 clips, recap host for
[audience]; publish every[weekday]. - Spoken script/audio brief: Cover
[three sourced items]. Name each date and owner, separate fact from analysis, and avoid predictions. - Action/expression prompt: Keep a measured expression, nod between items, and avoid excited reactions.
- Edit/CTA cue: Add dated source cards and links; end with
[source-list destination].
Replaceable variables: [audience] [weekday] [three sourced items] [source-list destination]
Production note: Verify every source, date, owner, and summary before publishing.
Success check:
- Can viewers trace each item to a dated source?
- Does the recap separate fact from interpretation?
47. Podcast Clip Introduction
Best for: Podcast Shorts, episode trailers, and archive clip resurfacing.
Concept: Add a brief, consistent orientation before a licensed podcast excerpt. Each post follows the same pattern: identify the speaker, state the question, give the source timestamp, then hand off. Publish one or more clips per episode on a fixed schedule. The avatar should never impersonate the guest or restate the excerpt as personal experience. Its only job is to supply context.
Video structure: Episode and speaker → question → timestamp → licensed excerpt.
Prompt — copy-ready input pack:
- Setup: 10 seconds, 9:16 plan, podcast guide for
[show audience]; publish[cadence]. - Spoken script/audio brief: Introduce
[speaker],[episode], and the question answered at[timestamp]. Add no facts beyond the source. - Action/expression prompt: Stay calm, nod before the handoff, and close still.
- Edit/CTA cue: Cut to the licensed excerpt; end with
[episode destination].
Replaceable variables: [show audience] [cadence] [speaker] [episode] [timestamp] [episode destination]
Production note: Confirm excerpt rights and add source audio only during editing.
Success check:
- Are the speaker, episode, and timestamp correct?
- Does the introduction avoid summarizing the answer?
48. Community Update Presenter
Best for: Membership groups, product communities, and event channels.
Concept: Deliver operational news with a fixed monthly or weekly bulletin format. Start with what changed, explain who it affects, and end with one dated action. The avatar acts as a disclosed community presenter, not a real moderator or member. Keep topic slots consistent across editions, such as event, resource, and deadline. Skip any slot that lacks an approved current update.
Video structure: Bulletin date → approved change → affected group → action and deadline.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 9:16 plan, disclosed host for
[community]; publish[cadence]. - Spoken script/audio brief: State
[approved update], its owner and date, who it affects, and[next action], without invented urgency. - Action/expression prompt: Stay welcoming, nod after the update, and hold still for the deadline.
- Edit/CTA cue: Add an approved date card and destination; repeat
[next action].
Replaceable variables: [community] [cadence] [approved update] [next action]
Production note: Obtain community-owner approval and exclude private member information.
Success check:
- Are the owner, date, and destination correct?
- Does the episode give one next action?
49. Reviewed Multilingual Social Video
Best for: Localized campaigns, regional help posts, and multilingual creator channels.
Concept: Adapt one approved message per locale instead of translating word for word. Keep structure and cadence consistent, but adapt examples, terms, pacing, and the CTA to local context. Talking Avatar supports multilingual audio workflows, yet a native reviewer must approve meaning and pronunciation. Never claim that the tool supplies automatic cultural or legal review.
Video structure: Approved message → locale adaptation → native review → matched publication.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 9:16 plan, regional host for
[locale audience]; publish[cadence]. - Spoken script/audio brief: Adapt
[approved message]into[target language]with current terms, natural pacing, and[locale CTA]. Use a permitted voice. - Action/expression prompt: Keep gaze, nod, and closing pose consistent across locales; match the reviewed tone.
- Edit/CTA cue: Add reviewed captions and regional links; end with
[locale CTA].
Replaceable variables: [locale audience] [cadence] [approved message] [target language] [locale CTA]
Production note: A native reviewer must approve each locale clip before publication.
Success check:
- Does a native reviewer approve the message?
- Do links reach the correct regional destination?
50. Original Brand Character Host
Best for: Weekly brand series, mascot explainers, and recurring creator formats.
Concept: Build a host around an original, brand-owned character with a documented role, voice, behavior, and sign-off. Each weekly episode keeps the same opening job and closing cue while changing one approved topic. This format creates continuity without borrowing a celebrity, fictional franchise character, or creator identity. The character should never claim real employment, experience, or product use unless those statements are truthful and approved.
Video structure: Recurring opening → episode job → one topic → sign-off and next action.
Prompt — copy-ready input pack:
- Setup: 20 seconds, 9:16 plan, original character for
[audience]; publish[cadence]. - Spoken script/audio brief: Explain
[episode topic]within[voice rules]. Avoid personal testimony, copied slogans, and unsupported claims. - Action/expression prompt: Follow the behavior guide, use one signature micro-expression, nod once, and close neutrally.
- Edit/CTA cue: Add approved brand assets; end with
[sign-off].
Replaceable variables: [audience] [cadence] [episode topic] [voice rules] [sign-off]
Production note: Use permitted assets and approve every identity-guide change.
Success check:
- Does the episode follow the identity guide?
- Does the character avoid impersonation and false claims?
Make the Avatar Easier to Watch
A good presenter clip does not need constant motion. Start with a clear, front-facing or slightly angled source. Keep the eyes and mouth visible. Match the voice to the role, then use short sentences and intentional pauses.
Break longer videos with relevant B-roll, slides, screen recordings, or product footage. If the product must remain exact, review the source and every generated insert. This guide on how to keep product visuals from warping covers the deeper visual checks.
Before publishing, ask:
- Does the mouth timing follow the audio without obvious drift?
- Do the expression and gestures support the line instead of distracting from it?
- Does every B-roll shot match the spoken point at that moment?
- Are product facts, interface labels, dates, captions, and disclosures accurate?
- Does the ending ask for one clear action?
If one answer is no, change the smallest relevant variable and generate the affected segment again.
Frequently Asked Questions
What makes a good talking avatar prompt?
A good prompt gives the speaker one role, one audience, one message, and one visible performance arc. Keep the spoken script, action prompt, supporting edit, and success criteria separate.
Should I put the script, action prompt, and edit plan in one field?
No. Put spoken wording in TTS or uploaded audio. Put visible expression and movement in the action prompt. Handle B-roll, captions, music, screen recordings, and precise cuts in the editing plan.
Can I use a talking avatar for UGC ads?
Yes, but disclose the avatar and avoid fake customer experiences. Use it as a fictional brand presenter, narrator, or demonstration guide. Support product claims with approved facts and owned or licensed footage.
What type of photo works best for a talking avatar?
Use a clear, well-lit image with one visible face, an unobstructed mouth, and a stable front-facing or slightly angled pose. Choose framing that already includes any body part named in the action prompt.
How long should a talking avatar video be?
Use the shortest clip that completes one job. Talking Avatar supports standard 5-, 10-, and 20-second clips. Longer ideas can use reviewed segments; 30- and 60-second fast mode is limited to Pro.
What rights or permissions do I need before publishing?
You need permission for the face, voice, source footage, product assets, logos, and other protected material you use. You also need to follow the destination platform’s current disclosure and synthetic-media rules. This is a production checklist, not legal advice.
Pick One Idea and Test the Smallest Version
Choose one idea, replace its variables, and make a 10- or 20-second pilot. Run the success checks, revise one variable, then build the longer edit only after the small version works.